Just a bit of insight: people are eager to build their own rigs for local LLMs, the same way we were obsessed with building gaming PCs 30 years ago. x.com/i/chat/group_j…
Turns out you can tune Strata for more prefill speed. On Qwen3.8-Flash Q6-KXL setup: +72% prefill on short context, +27% on long context, and VRAM hit rate stays pinned at 100%. The main knobs are --pcie-frac, layer_split, and --trim-stage-weights. The catch: MTP still isn’t
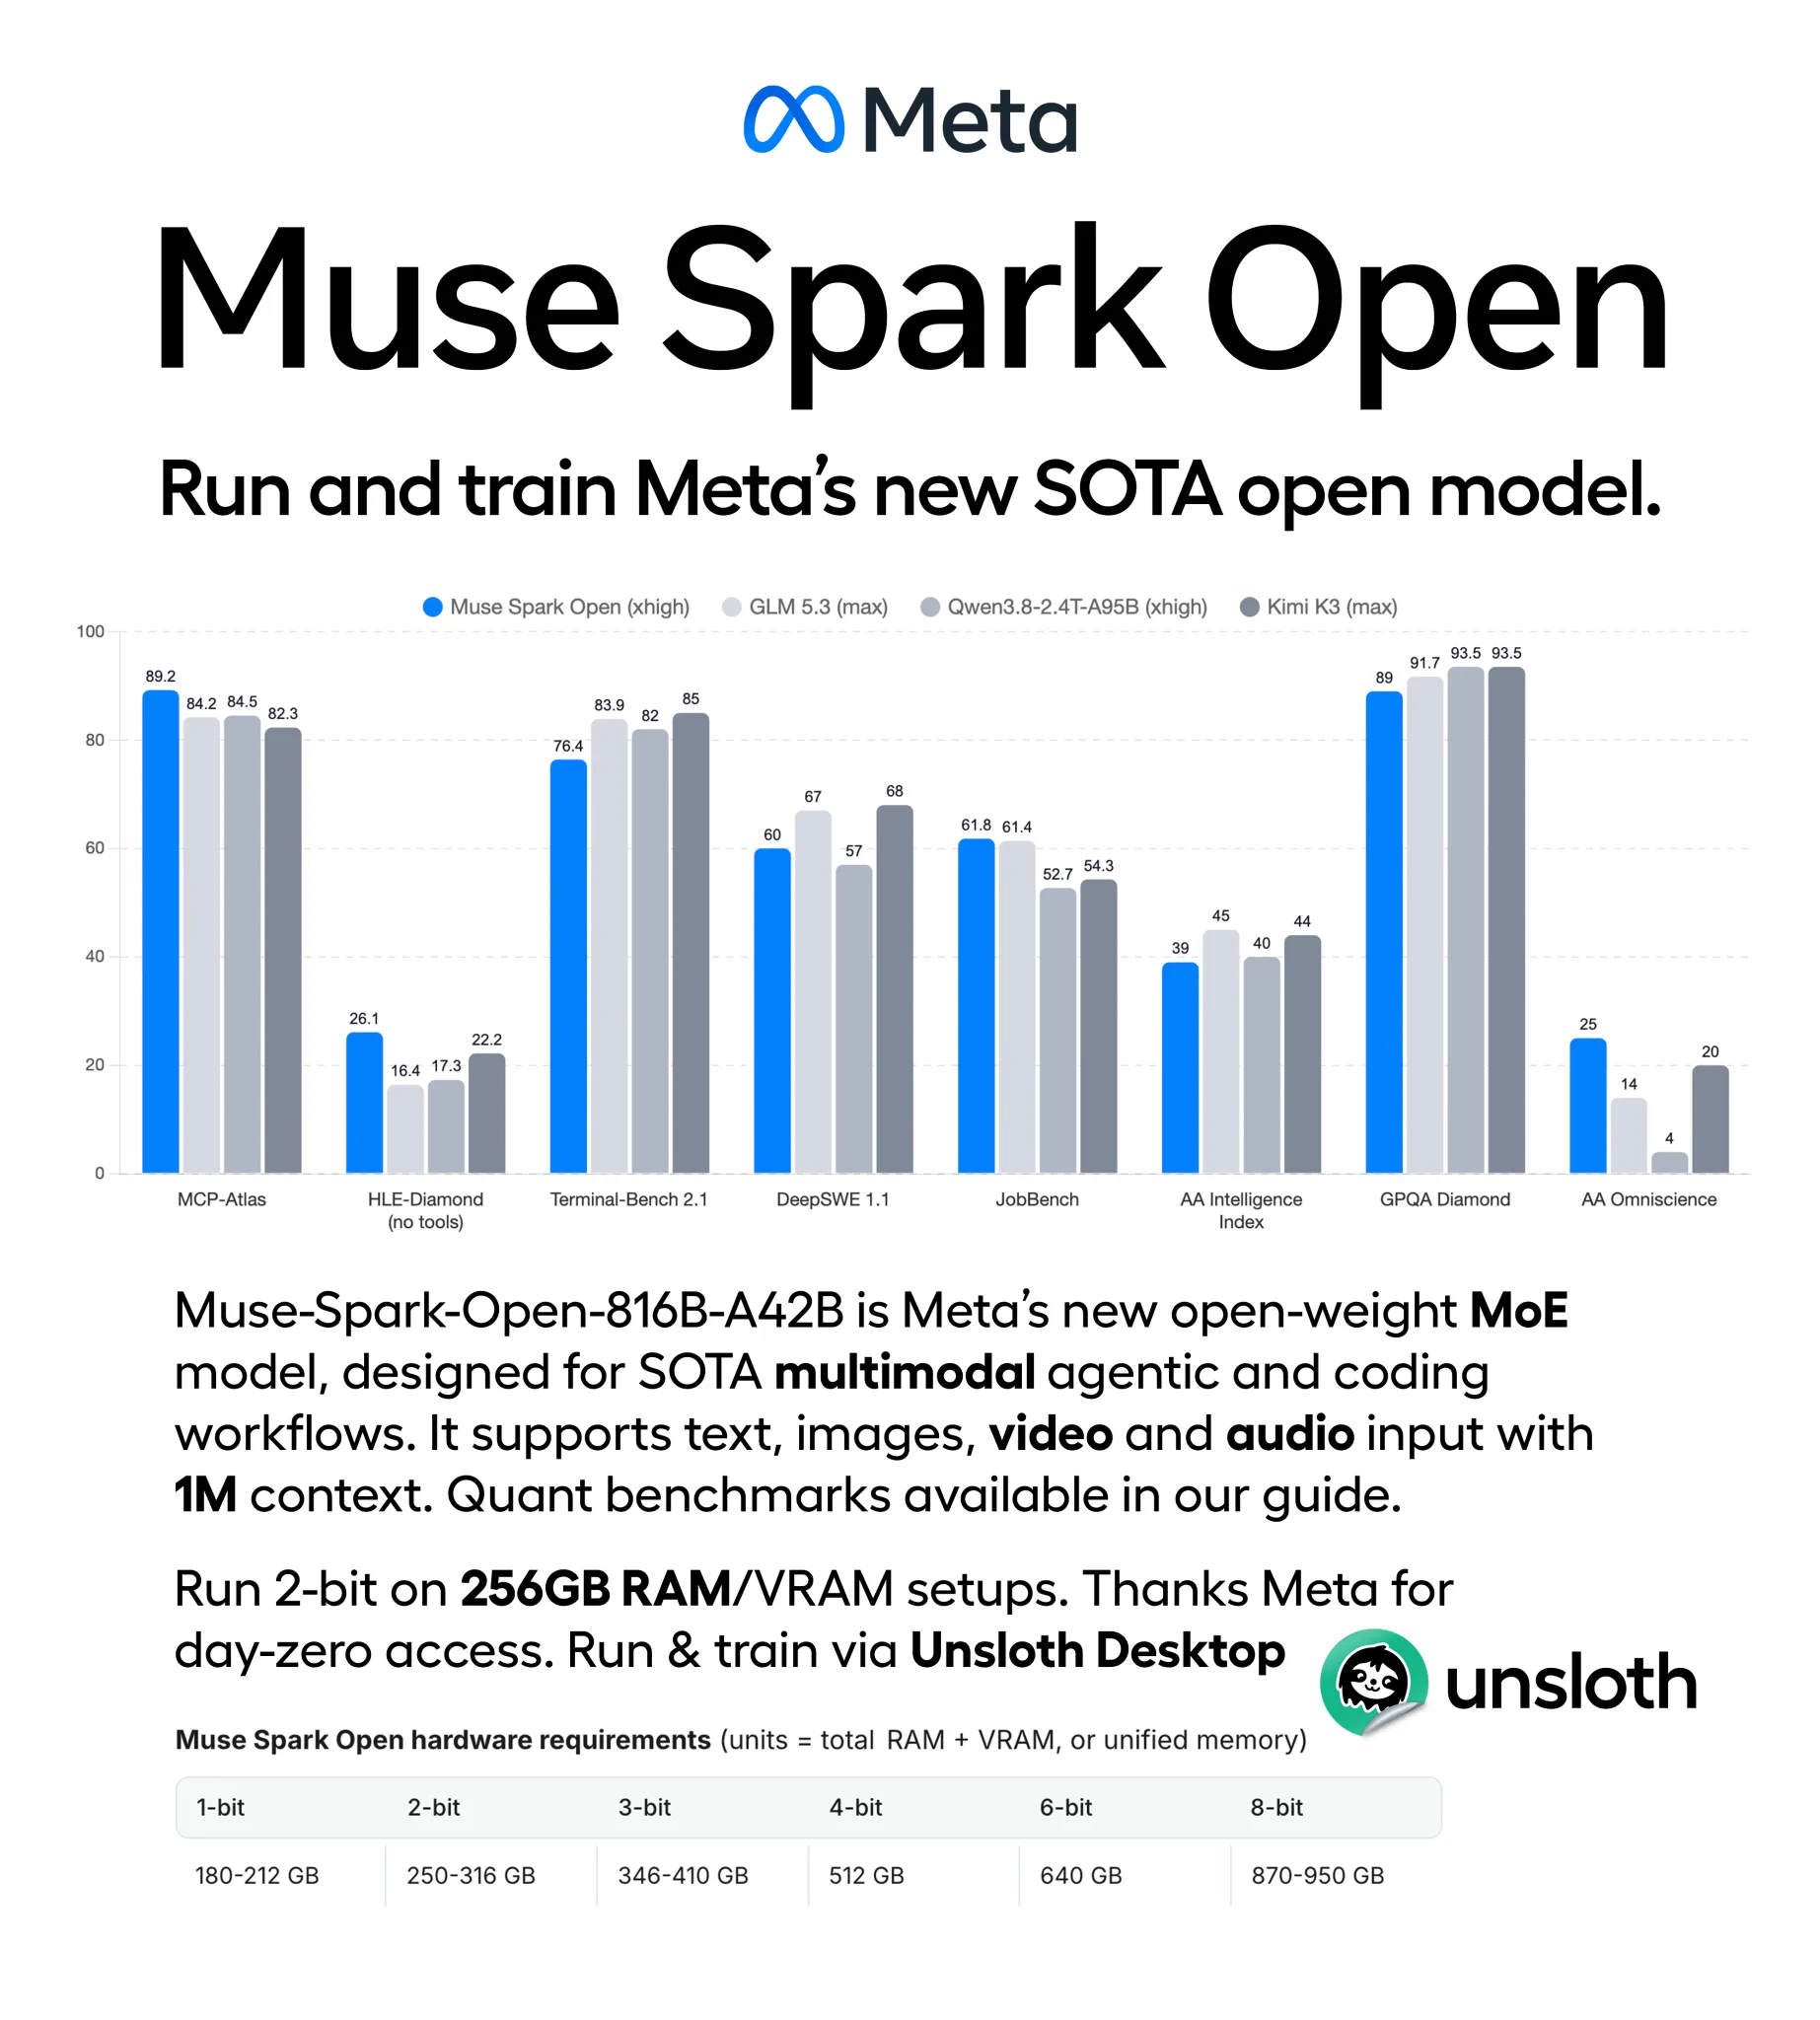
Meta releases Muse Spark Open, a new SOTA open model.
Run on a Mac Studio via Dynamic 2-bit Unsloth GGUFs.
Muse-Spark-Open-816B-A42B supports text, images, video and audio input with 1M context.
GGUF: huggingface.co/unsloth/Muse-S…
Guide: unsloth.ai/docs/models/mu…
NVIDIA releases 2 new models: Nemotron-3.5-Bolt and Nemotron-3.5-Super-VL.
Nemotron-3.5-Bolt-74B-A9B runs on 24GB RAM. It delivers top-tier performance for its size.
Super-VL-120B-A12B runs on 82GB RAM.
Bolt GGUF: huggingface.co/unsloth/NVIDIA…
Guide: unsloth.ai/docs/models/ne…
Super