
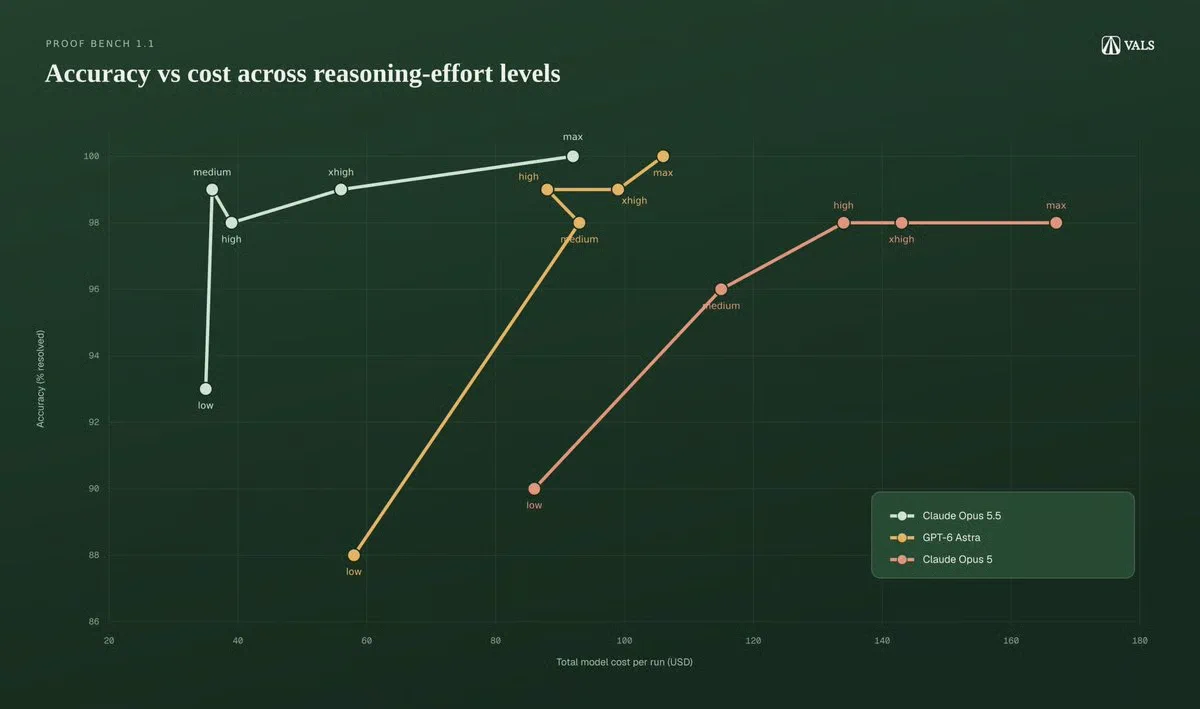
GPT-6 Astra got more proofs right at high than at medium in Vals AI's ProofBench v1.1 tests. Each turn cost about $0.70 more, but 117 fewer turns made the whole run cheaper.
Vals tested Astra, Claude Opus 5, and Opus 5.5 at five reasoning levels, from low to max. Opus 5.5 scored 99% at medium for ~$36 per 100-problem run. At max, it reached 100% for ~$92. The last percentage point cost another $56. Astra also hit 100% at max, for ~$106.
Opus 5 plateaued at 98% from high through xhigh and max. At max, it used ~4.4M tokens and cost ~$167 without solving the remaining two problems. More budget brought no accuracy gain on this set with this harness.
ProofBench covers advanced undergraduate and graduate math, with 100 public and 100 private problems. Lean experts, including mathematics PhD researchers, formalized and reviewed them. Models receive both natural-language and Lean 4 statements and must submit proofs accepted by Lean.
The website's full leaderboard, from a separate evaluation run, lists Opus 5.5, Claude Fable 5.1, and AlephProver at 100%. AlephProver averaged $9.35 per problem versus Opus 5.5's ~$0.92: roughly ten times the cost for the same score.
vals.ai/benchmarks/pro…
- GPT-6 Astra got more proofs right at high than at medium in Vals AI's ProofBench v1.1 tests. Each turn cost about $0.70 more, but 117 fewer turns made the whole run cheaper. Vals tested Astra, Claude Opus 5, and Opus 5.5 at five reasoning levels, from low to max. Opus 5.5 scored 99% at medium for ~$36 per 100-problem run. At max, it reached 100% for ~$92. The last percentage point cost another $56. Astra also hit 100% at max, for ~$106. Opus 5 plateaued at 98% from high through xhigh and max. At max, it used ~4.4M tokens and cost ~$167 without solving the remaining two problems. More budget brought no accuracy gain on this set with this harness. ProofBench covers advanced undergraduate and graduate math, with 100 public and 100 private problems. Lean experts, including mathematics PhD researchers, formalized and reviewed them. Models receive both natural-language and Lean 4 statements and must submit proofs accepted by Lean. The website's full leaderboard, from a separate evaluation run, lists Opus 5.5, Claude Fable 5.1, and AlephProver at 100%. AlephProver averaged $9.35 per problem versus Opus 5.5's ~$0.92: roughly ten times the cost for the same score. vals.ai/benchmarks/pro…
 100% proofs for $100 is insane. Opus 5.5 efficiency wins
 The cost-versus-reasoning tradeoff here is fascinating. More compute clearly doesn't always mean better results.