
Download the free Kindle app and start reading Kindle books instantly on your smartphone, tablet, or computer - no Kindle device required.
Read instantly on your browser with Kindle for Web.
Using your mobile phone camera - scan the code below and download the Kindle app.
Follow the author
OK
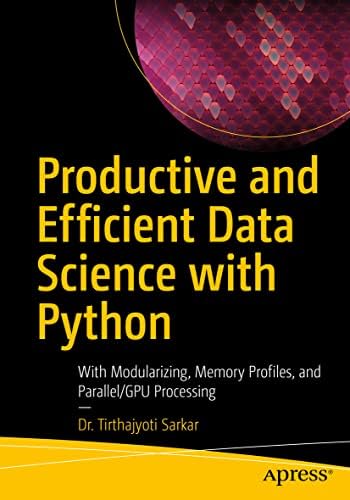
Productive and Efficient Data Science with Python: With Modularizing, Memory profiles, and Parallel/GPU Processing
Purchase options and add-ons
This book focuses on the Python-based tools and techniques to help you become highly productive at all aspects of typical data science stacks such as statistical analysis, visualization, model selection, and feature engineering.
You’ll review the inefficiencies and bottlenecks lurking in the daily business process and solve them with practical solutions. Automation of repetitive data science tasks is a key mindset that is promoted throughout the book. You’ll learn how to extend the existing coding practice to handle larger datasets with high efficiency with the help of advanced libraries and packages that already exist in the Python ecosystem.
The book focuses on topics such as how to measure the memory footprint and execution speed of machine learning models, quality test a data science pipelines, and modularizing a data science pipeline for app development. You’ll review Python libraries which come in very handy for automating and speeding up the day-to-day tasks.
In the end, you’ll understand and perform data science and machine learning tasks beyond the traditional methods and utilize the full spectrum of the Python data science ecosystem to increase productivity.What You’ll Learn
- Write fast and efficient code for data science and machine learning
- Build robust and expressive data science pipelines
- Measure memory and CPU profile for machine learning methods
- Utilize the full potential of GPU for data science tasks
- Handle large and complex data sets efficiently
Who This Book Is For
Data scientists, data analysts, machine learning engineers, Artificial intelligence practitioners, statisticians who want to take full advantage of Python ecosystem.
- ISBN-101484281209
- ISBN-13978-1484281208
- EditionFirst Edition
- Publication dateJuly 2, 2022
- LanguageEnglish
- Dimensions7.01 x 0.92 x 10 inches
- Print length404 pages
Similar items that may deliver to you quickly
- Ultimate Parallel and Distributed Computing with Julia For Data Science: Excel in Data Analysis, Statistical Modeling and Machine Learning by ... Programming — Parallel Systems Path)Nabanita DashPaperbackFREE Shipping by AmazonGet it as soon as Sunday, Oct 11
- Deep Learning with C++: Design and deploy neural networks using CUDA for high-performance AI in C++PaperbackFREE Shipping by AmazonGet it as soon as Sunday, Oct 11
- Fast Python: High performance techniques for large datasetsPaperbackFREE ShippingGet it Oct 26 - Nov 2Usually ships within 7 to 8 days
- GPU-Accelerated Computing with Python 3 and CUDA: From low-level kernels to real-world applications in scientific computing and machine learningPaperbackFREE Shipping by AmazonGet it as soon as Sunday, Oct 11
- AI Systems Performance Engineering: Optimizing Model Training and Inference Workloads with GPUs, CUDA, and PyTorchPaperbackFREE Shipping by AmazonGet it as soon as Sunday, Oct 11
- Data Algorithms with Spark: Recipes and Design Patterns for Scaling Up using PySparkPaperbackFREE Shipping by AmazonGet it as soon as Sunday, Oct 11Only 9 left in stock (more on the way).
Editorial Reviews
From the Back Cover
This book focuses on the Python-based tools and techniques to help you become highly productive at all aspects of typical data science stacks such as statistical analysis, visualization, model selection, and feature engineering.
You’ll review the inefficiencies and bottlenecks lurking in the daily business process and solve them with practical solutions. Automation of repetitive data science tasks is a key mindset that is promoted throughout the book. You’ll learn how to extend the existing coding practice to handle larger datasets with high efficiency with the help of advanced libraries and packages that already exist in the Python ecosystem.
The book focuses on topics such as how to measure the memory footprint and execution speed of machine learning models, quality test a data science pipelines, and modularizing a data science pipeline for app development. You’ll review Python libraries which come in very handy for automating and speeding up the day-to-day tasks.
In the end, you’ll understand and perform data science and machine learning tasks beyond the traditional methods and utilize the full spectrum of the Python data science ecosystem to increase productivity.You will:
- Write fast and efficient code for data science and machine learning
- Build robust and expressive data science pipelines
- Measure memory and CPU profile for machine learning methods
- Utilize the full potential of GPU for data science tasks
- Handle large and complex data sets efficiently
About the Author
He has published data science books, and regularly contributes highly cited AI/ML-related articles on top platforms such as KDNuggets and Towards Data Science. Tirthajyoti has developed multiple open-source software packages in the field of statistical modeling and data analytics. He has 5 US patents and more than thirty technical publications in international journals and conferences.
He conducts regular workshops and participates in expert panels on various AI/ML topics and contributes tothe broader data science community in numerous ways. Tirthajyoti holds a Ph.D. from the University of Illinois and a B.Tech degree from the Indian Institute of Technology, Kharagpur.
Product details
- Publisher : Apress
- Publication date : July 2, 2022
- Edition : First Edition
- Language : English
- Print length : 404 pages
- ISBN-10 : 1484281209
- ISBN-13 : 978-1484281208
- Item Weight : 1.55 pounds
- Dimensions : 7.01 x 0.92 x 10 inches
- Best Sellers Rank: #7,053,896 in Books (See Top 100 in Books)
- #1,128 in Unix Operating System
- #5,772 in Database Storage & Design
- #6,291 in Python Programming
About the author

Dr. Tirthajyoti Sarkar currently works as the Sr. VP, AI/ML, at Rhombus Power Inc. where he is building solutions for problems of vital national and global importance with AI, data, and mathematics. He is a prolific author having published top-selling books in the domain of data science and statistics.
Prior to that, he worked as Data Science Engineering Manager at a startup developing edge-computing platforms for the semiconductor manufacturing industry. Before that, he spent more than a decade in the semiconductor and electronics industry where he developed power semiconductor technology and applied Artificial Intelligence and Machine Learning techniques for design automation and product innovation.
Dr. Sarkar regularly publishes AI and data science articles on top online platforms and teaches machine learning in various workshops and forums. He has published 30+ papers in IEEE and holds multiple US patents. Dr. Sarkar is a Sr. Member of IEEE, a former Chair of the Semiconductor Committee of the PSMA (world's largest power supply organization consortium), and an Industry Advisory Member for ValleyML, a non-profit AI/ML organization. He holds a Ph.D. in Electrical Engineering from the Univ. of Illinois at Chicago and MS in Data Analytics from Georgia Tech.
Customer reviews
- 5 star4 star3 star2 star1 star5 star0%0%0%0%0%0%
- 5 star4 star3 star2 star1 star4 star0%0%0%0%0%0%
- 5 star4 star3 star2 star1 star3 star0%0%0%0%0%0%
- 5 star4 star3 star2 star1 star2 star0%0%0%0%0%0%
- 5 star4 star3 star2 star1 star1 star0%0%0%0%0%0%
Customer Reviews, including Product Star Ratings help customers to learn more about the product and decide whether it is the right product for them.
To calculate the overall star rating and percentage breakdown by star, we don’t use a simple average. Instead, our system considers things like how recent a review is and if the reviewer bought the item on Amazon. It also analyzed reviews to verify trustworthiness.
Learn more how customers reviews work on Amazon