Just a bit of insight: people are eager to build their own rigs for local LLMs, the same way we were obsessed with building gaming PCs 30 years ago. x.com/i/chat/group_j…
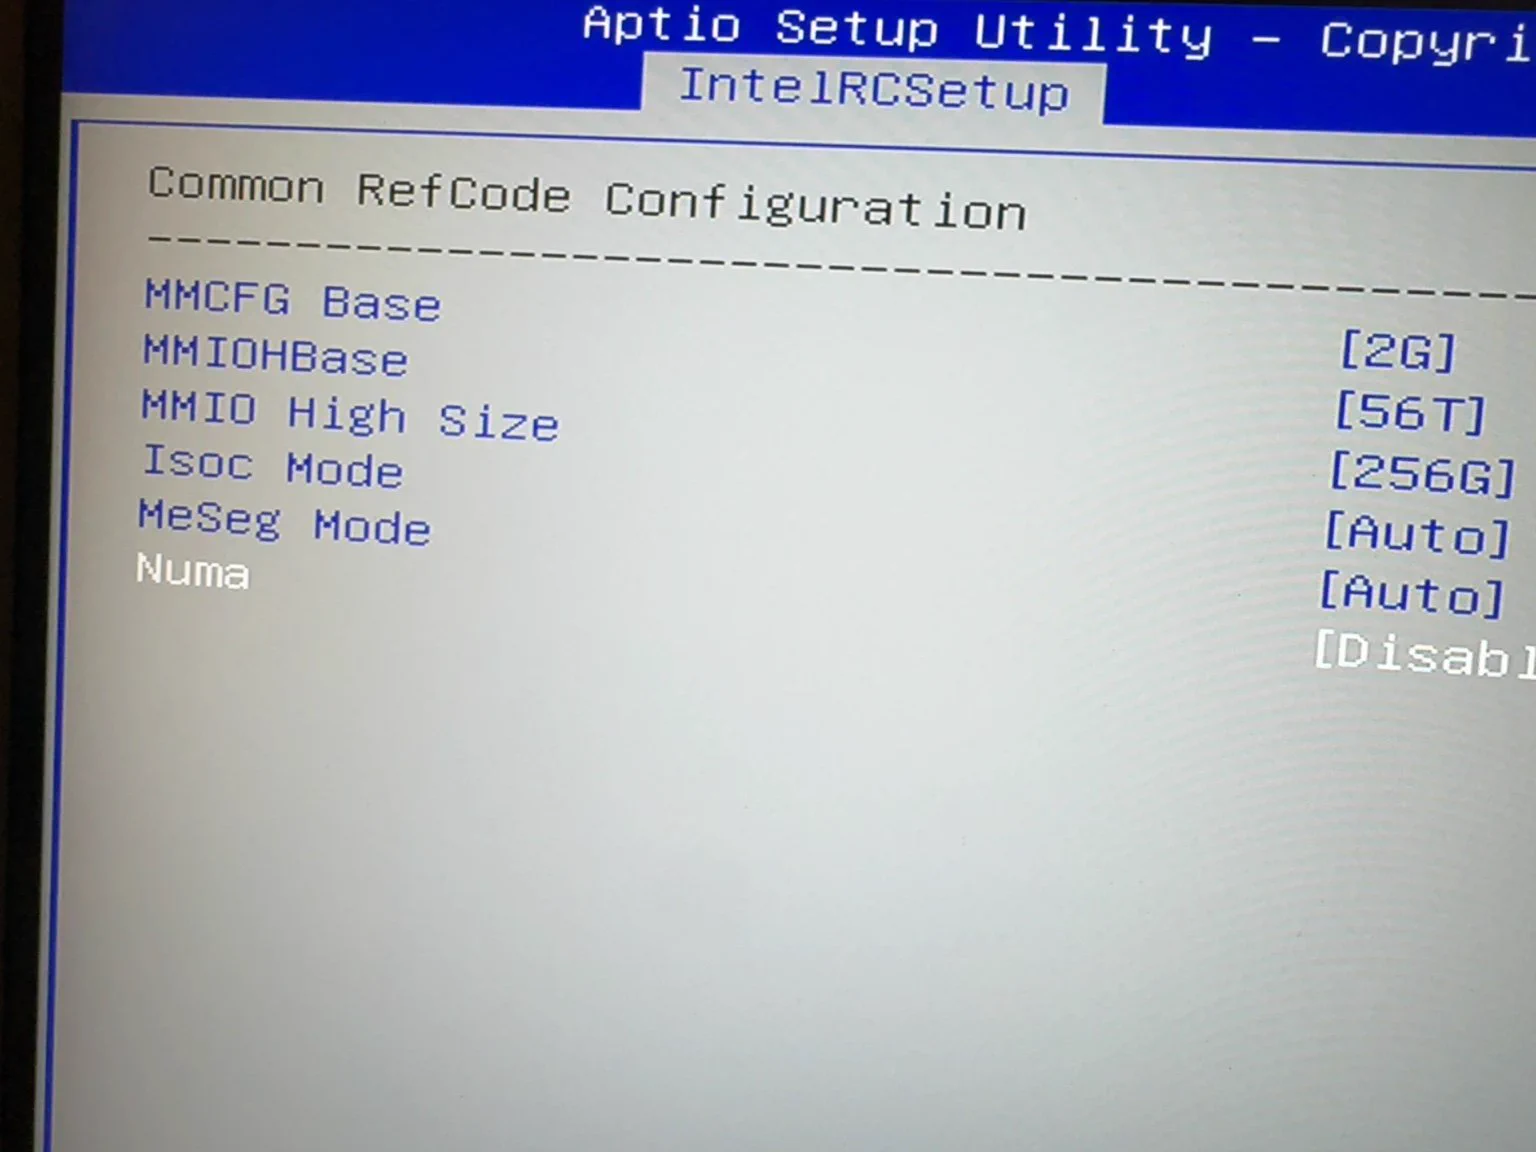
PSA for dual-socket CPUs owners: So check your BIOS and enable NUMA(some boards label it “Node Interleaving”). With NUMA enabled, Strata gets another long-context boost: prefill up to +19%, decode up to +20%.
Just did my last upgrade of the year: added another 2×32GB RAM. My local LLM rig 4x100 96G VRAM + 192G RAM is now complete. 128GB was already plenty, but I’m prepping for new models (Qwen4-Flash?)—or maybe one day Strata makes Q6 as fast as Q4. Add 1M context to that? Absolutely
🥰Thanks for the follow! Local LLMs are getting so much attention—I gained 1,000+ new followers in one week. Let's enjoy local LLMs together, like everyone building their own Jarvis at home. 🤖
🍻1M context! Strata surprised me again. After loading Qwen3.8-Flash Q4_K_XL, my rig still had lots of RAM left, so I cranked Strata’s context window all the way to 1M—the maximum this model supports. Guess what? It only added 30GB of RAM, and the decode/prefill speed drop is