Repository navigation
CUDA: Fix source location on kernel entry and enable breakpoints to be set on kernels by mangled name - #6841
Conversation


Marking a subprogram, variable, or location in the DIBuilder API
requires passing in a `numba.core.ir.Loc` object. This makes sense when
all debuginfo generation comes from lowering, but creates weird
dependencies when generating code that doesn't relate to a specific
piece of IR - for example, the kernel wrapper generated in the CUDA
target. To mark locations in the kernel wrapper, one must import the
`Loc` class from `numba.core.ir`, and construct instances of it to pass
in, just to mark locations in generated code (or do something more odd
with a "pretend" `Loc` object).

Since the `Loc` instances are only used for the line number, this commit
changes the interface of the relevant `DIBuilder` methods to accept a
line number instead of a `Loc`, breaking the spurious coupling.
Doing this provides a couple of improvements:

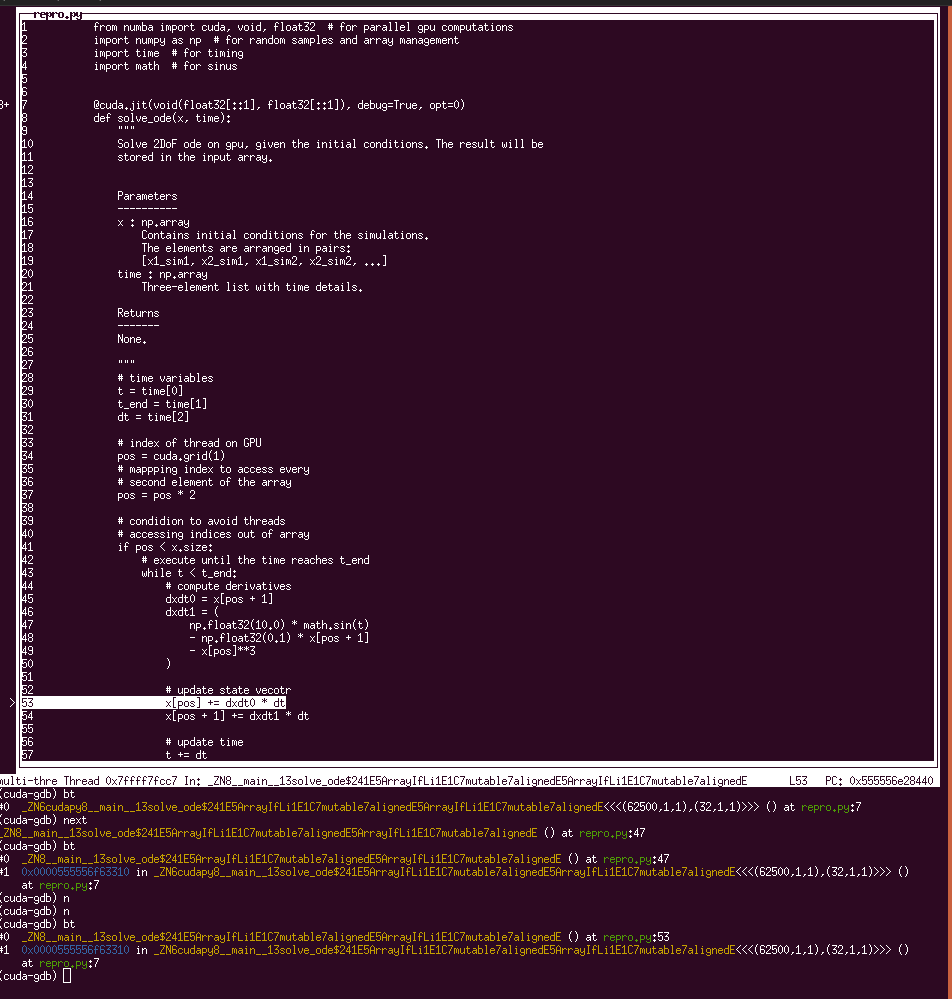
- Breaking on any kernel launch, for example with
  `set cuda break_on_launch application` now results in GDB being able
  to find the source line at the break location - this enables the
  backtrace to show the mangled function name, source file, and line
  number. It also enables the text user interface to display the source
  when the kernel launches. From this point, stepping through
  line-by-line is feasible with the `next` command.
- Breakpoints can be set on a specific function and argument types, by
  setting a breakpoint on the mangled name.

(neither of these worked prior to this change)

Issues that remain include:

- GDB doesn't demangle the names of functions, like it seems to in the
  CPU target examples. Oddly, the act of marking the subprogram seems to
  break demangling - prior to this commit, the location of the wrapper
  kernel isn't known, but it does demangle correctly.
- Most locals appear to be optimized out even with `opt=0`. This also
  needs further investigation.
 gmarkall
changed the title

| } | ||
|
|
||
| tgt_ctx = cres.target_context | ||
| filename = cres.type_annotation.filename |
There was a problem hiding this comment.
It's weird that I have to get the source file name from the type annotation at this stage, but I think the function IR is now lost (it was never saved after the pipeline finished).
There was a problem hiding this comment.
It's probably in the self.py_func.__code__.co_filename and cres.fndesc.lookup_module.__file__ too if they are preferable? IIRC the compile result doesn't hold reference to the IR as the IR could hold reference to e.g. globals, some of which might be large (e.g. NumPy arrays) and this would create memory pressure etc.
|
|
||
| tgt_ctx = cres.target_context | ||
| filename = cres.type_annotation.filename | ||
| linenum = int(cres.type_annotation.linenum) |
There was a problem hiding this comment.
Also, the line number being a string in the type annotation is a minor problem, as LLVM expects line numbers to be integers (e.g. 5), not strings ("5").
There was a problem hiding this comment.
foo.py_func.__code__.co_firstlineno might help, as might inspect module?

|
Example of the text user interface showing source layout and backtrace (start of the kernel is repro.py line 7, the wrapper function name begins
|
 gmarkall
added
3 - Ready for Review
Effort - medium
|
A couple more notes on the lack of un-mangling in cuda-gdb: For the CUDA target, whereas on the CPU target the At the moment the name and the linkage name are the same for each subprogram, e.g.: instead of However, for device functions the Fixing these alone doesn't seem to help (I've tried locally by applying): diff --git a/numba/cuda/cudadrv/nvvm.py b/numba/cuda/cudadrv/nvvm.py
index c77ec456e..35ab0a260 100644
--- a/numba/cuda/cudadrv/nvvm.py
+++ b/numba/cuda/cudadrv/nvvm.py
@@ -776,6 +777,9 @@ def llvm100_to_70_ir(ir):
attrs = ' '.join(a for a in attrs if a != 'willreturn')
line = line.replace(m.group(1), attrs)
+ if '= distinct !DICompileUnit' in line:
+ line = line.replace('emissionKind: 1', 'emissionKind: FullDebug')
+
buf.append(line)
return '\n'.join(buf)
diff --git a/numba/cuda/target.py b/numba/cuda/target.py
index 090c58d34..82c21c794 100644
--- a/numba/cuda/target.py
+++ b/numba/cuda/target.py
@@ -145,12 +145,13 @@ class CUDATargetContext(BaseContext):
nvvm_options=nvvm_options,
max_registers=max_registers)
library.add_linking_library(codelib)
- wrapper = self.generate_kernel_wrapper(library, kernel_name, func_name,
+ wrapper = self.generate_kernel_wrapper(library, codelib.name,
+ kernel_name, func_name,
argtypes, debug, filename,
linenum)
return library, wrapper
- def generate_kernel_wrapper(self, library, kernel_name, func_name,
+ def generate_kernel_wrapper(self, library, py_name, kernel_name, func_name,
argtypes, debug, filename, linenum):
"""
Generate the kernel wrapper in the given ``library``.
@@ -172,7 +173,10 @@ class CUDATargetContext(BaseContext):
if debug:
debuginfo = self.DIBuilder(module=wrapper_module, filepath=filename)
- debuginfo.mark_subprogram(wrapfn, kernel_name, linenum)
+ debuginfo.mark_subprogram(wrapfn, py_name, linenum)
debuginfo.mark_location(builder, linenum)
# Define error handling variablesSince it doesn't help I've not added it to this PR - I'd prefer only to add things that clearly make improvements - are there any other thoughts on what might be missing for mangling to work here? |
|
(Popping this back to "In progress" because I just noticed it breaks with NVVM 3.4, and needs #5311 fixing for it to work) |
Includes:

- Calls `llvm_to_ptx` once for each IR module when compiling for debug.
- Don't adjust linkage of functions in linked modules when debugging,
  because we need device functions to be externally visible.
- Fixed setting of NVVM options when calling `compile_cuda` from kernel
  compilation and device function template compilation.
- Removes `debug_pubnames` patch.

Outcomes:

- The "Error: Debugging support cannot be enabled when number of debug
  compile units is more than 1" message is no longer produced with NVVM
  3.4.
- NVVM 7.0: Everything still seems to "work" as much as it did before.
  Stepping may be more stable, but this needs a bit more verification.

Fixes numba#5311.
|
I've included a fix for #5311 in this branch now - this resolves the long-standing "Error: Debugging support cannot be enabled when number of debug compile units is more than 1" message. |
|
I think this is ready for review - looks like I somehow forgot to mark it as such. |

|
Buildfarm ID: |
Passed. |
|
@gmarkall please could you resolve the conflicts? then I'll look to review this, thanks. |
 stuartarchibald
added
4 - Waiting on author
gmarkall
added
4 - Waiting on reviewer
|
@stuartarchibald conflicts now resolved. |
| filename: The source filename that the function is contained in. | ||
| linenum: The source line that the function is on. |
There was a problem hiding this comment.
What happens if someone materialized a function from a string?
There was a problem hiding this comment.
filename is <string> and linenum is the line in the string on which the function began - I think this is normal / expected?
 stuartarchibald
left a comment
stuartarchibald
left a comment
There was a problem hiding this comment.
Thanks for the patch, I've taken a first look through it but would like to do some manual testing. There's a few minor things to look at and some questions/suggestions above. Thanks again!
stuartarchibald
added
4 - Waiting on author
- Use `self.py_func.__code__` to get the filename and line number for
  the function for `prepare_cuda_kernel`, which seems a bit cleaner /
  neater that digging into the type annotation for it.
- Fix typo and explicitly link to an issue comment.
|
@stuartarchibald Thanks for the review and suggestions! All comments should be addressed now. |
gmarkall
added
4 - Waiting on reviewer

|
Build Farm ID: |

stuartarchibald
left a comment
stuartarchibald
left a comment
There was a problem hiding this comment.
Thanks for the patch and fixes.
stuartarchibald
added
4 - Waiting on CI
|
Note: I manually verified this patch: $ cuda-gdb --args python add_one.py
<snip>
Reading symbols from python...
(cuda-gdb) set cuda break_on_launch application
(cuda-gdb) r
Starting program: bin/python add_one.py
[Thread debugging using libthread_db enabled]
Using host libthread_db library "/lib64/libthread_db.so.1".
[Detaching after fork from child process 7719]
[Detaching after fork from child process 7720]
[Detaching after fork from child process 7721]
[Detaching after fork from child process 7724]
[New Thread 0x7fffda69b700 (LWP 7731)]
[New Thread 0x7fffd9e9a700 (LWP 7732)]
[New Thread 0x7fffd9699700 (LWP 7733)]
numba/cuda/compiler.py:865: NumbaPerformanceWarning: Grid size (1) < 2 * SM count (26) will likely result in GPU under utilization due to low occupancy.
warn(NumbaPerformanceWarning(msg))
[Switching focus to CUDA kernel 0, grid 1, block (0,0,0), thread (0,0,0), device 0, sm 0, warp 0, lane 0]
0x0000555556b98c88 in _ZN6cudapy8__main__20increment_by_one$241E5ArrayIdLi1E1C7mutable7alignedE<<<(1,1,1),(1,1,1)>>> ()
at add_one.py:4
4 @cuda.jit(debug=True, opt=0)
(cuda-gdb) l
1 import numpy as np
2 from numba import cuda
3
4 @cuda.jit(debug=True, opt=0)
5 def increment_by_one(an_array):
6 # Thread id in a 1D block
7 tx = cuda.threadIdx.x
8 # Block id in a 1D grid
9 ty = cuda.blockIdx.x
10 # Block width, i.e. number of threads per block
(cuda-gdb) s
0x0000555556b7f168 in _ZN8__main__20increment_by_one$241E5ArrayIdLi1E1C7mutable7alignedE () at add_one.py:4
4 @cuda.jit(debug=True, opt=0)
(cuda-gdb) s
7 tx = cuda.threadIdx.x
(cuda-gdb) s
13 pos = tx + ty * bw
(cuda-gdb) s
14 if pos < an_array.size: # Check array boundaries |
 esc
added
5 - Ready to merge
3 participants


This PR improves a couple of aspects of debugging in CUDA:
set cuda break_on_launch applicationnow results in GDB being able to find the source line at the break location - this enables the backtrace to show the mangled function name, source file, and line number. It also enables the text user interface to display the source when the kernel launches. From this point, stepping throughline-by-line is feasible with the
nextcommand.(neither of these worked prior to this change).
This PR also separates the DIBuilder API from the Numba IR API in the first commit, to avoid building Numba IR for no reason (or strange reasons) when generating the kernel wrapper.
There's still a little API weirdness that bothers me, but I'm not sure I can see the better way - perhaps the reviewer can suggest an improvement (I'll comment on the diff).