Project Frankenstein
A multi-tenant, horizontally scalable Prometheus as a Service
Tom Wilkie (& Julius Volz)
Weaveworks, August 2016
“the best way to visualise, manage & monitor your cloud
native application”
Design
why not just run my own Prometheus?
• the as-a-service bit provides authentication and
access control
• virtually infinite retention; all the state is managed
for you, by us
• provide a different story around durability, HA and
scalability
• (eventually) better query performance, especially
for long queries
requirements:
1. API compatible with Prometheus
2. easy to operate and manage
3. tens of thousands of users, tens of
millions samples/s
4. cost effective to run
5. reuse as much of Prometheus as possible
… so we can sell it
Aim: build proof of concept as
quickly as possible
16/06 started design doc
22/06 circulated on list
22/06 initial commit
26/07 launch jobs
25/08 give talk!
http://goo.gl/prdUYV
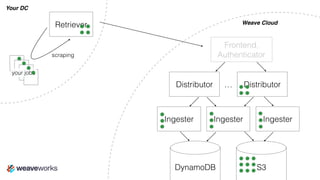
Retriever
scraping
your jobs
Your DC
Weave Cloud
Frontend,
Authenticator
Distributor
Ingester
Distributor…
IngesterIngester
DynamoDB S3
Retriever
/bin/prometheus -retrieval-only -storage.remote.generic-url=...
Does scraping and relabelling.
Is a vanilla Prometheus plus:
• Brian Brazil’s generic write PR (#1487)
• Some modification to prevent local storage + indexing
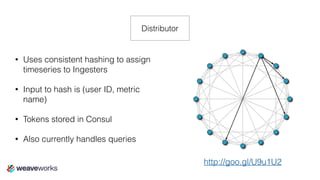
• Uses consistent hashing to assign
timeseries to Ingesters
• Input to hash is (user ID, metric
name)
• Tokens stored in Consul
• Also currently handles queries
Distributor
http://goo.gl/U9u1U2
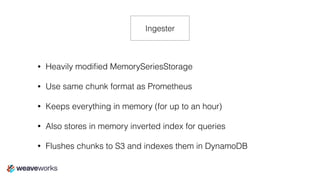
• Heavily modified MemorySeriesStorage
• Use same chunk format as Prometheus
• Keeps everything in memory (for up to an hour)
• Also stores in memory inverted index for queries
• Flushes chunks to S3 and indexes them in DynamoDB
Ingester
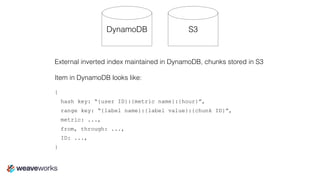
External inverted index maintained in DynamoDB, chunks stored in S3
Item in DynamoDB looks like:
{
hash key: “{user ID}:{metric name}:{hour}”,
range key: “{label name}:{label value}:{chunk ID}”,
metric: ...,
from, through: ...,
ID: ...,
}
DynamoDB S3
Evaluation
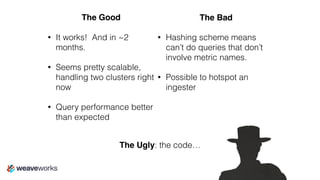
The Good
• It works! And in ~2
months.
• Seems pretty scalable,
handling two clusters right
now
• Query performance better
than expected
The Ugly: the code…
The Bad
• Hashing scheme means
can’t do queries that don’t
involve metric names.
• Possible to hotspot an
ingester
Demo
Lots left to do…
Features:
• Recording rules
• Alerting & Alertmanager
Reliability:
• Replication between
ingesters, commit log etc
• Ingestor lifecycle
• Separate query service?
Performance:
• Query parallelisation
• Background chunk
coalescing
Code:
• Code cleanup
• Upstream appropriate
changes
Questions?
Try it out!
Email help@weave.works for
instructions and to get on white list
https://github.com/tomwilkie/prometheus